The steps
- Check ordinary selection
Try selecting the passage in your PDF viewer first. Use capture when the page behaves like an image.
- Enlarge the passage
Zoom to a clear section of the page and ensure every required line is visible.
- Capture the words
Choose Capture Text in LensOCR and select the passage on screen.
- Paste and compare
Paste the extract into a document, add its page reference, and check it against the PDF.
Check whether the PDF already has selectable text
Open the PDF in Preview or your usual PDF viewer and try selecting a sentence. Some scanned documents already include a recognized text layer, even though their pages look like photographs. If selection works, copy directly and inspect the result. That avoids running another recognition pass over text that is already available.
If you can only select the page as an image, screen OCR gives you a way to recover a passage. The same approach can help when an embedded diagram or a photographed attachment contains words that the surrounding document does not expose as selectable text. Work from the visible source and keep the relevant page open.
Zoom the scanned page to a readable size
A full page displayed inside a small window can make the characters too small to distinguish. Increase the PDF viewer's zoom until the passage is clear. Focus on the section you need rather than fitting the entire page onto the screen. Check that the right edge of a line is not hidden outside the window.
Rotate a sideways page in the viewer before capturing it. A scan with faded print, shadows, or a fold across the letters may still require manual corrections. If you have access to a cleaner scan, use it. Zoom makes existing detail easier to see, but it cannot reconstruct characters that are missing from the source.
Capture a paragraph or one column at a time
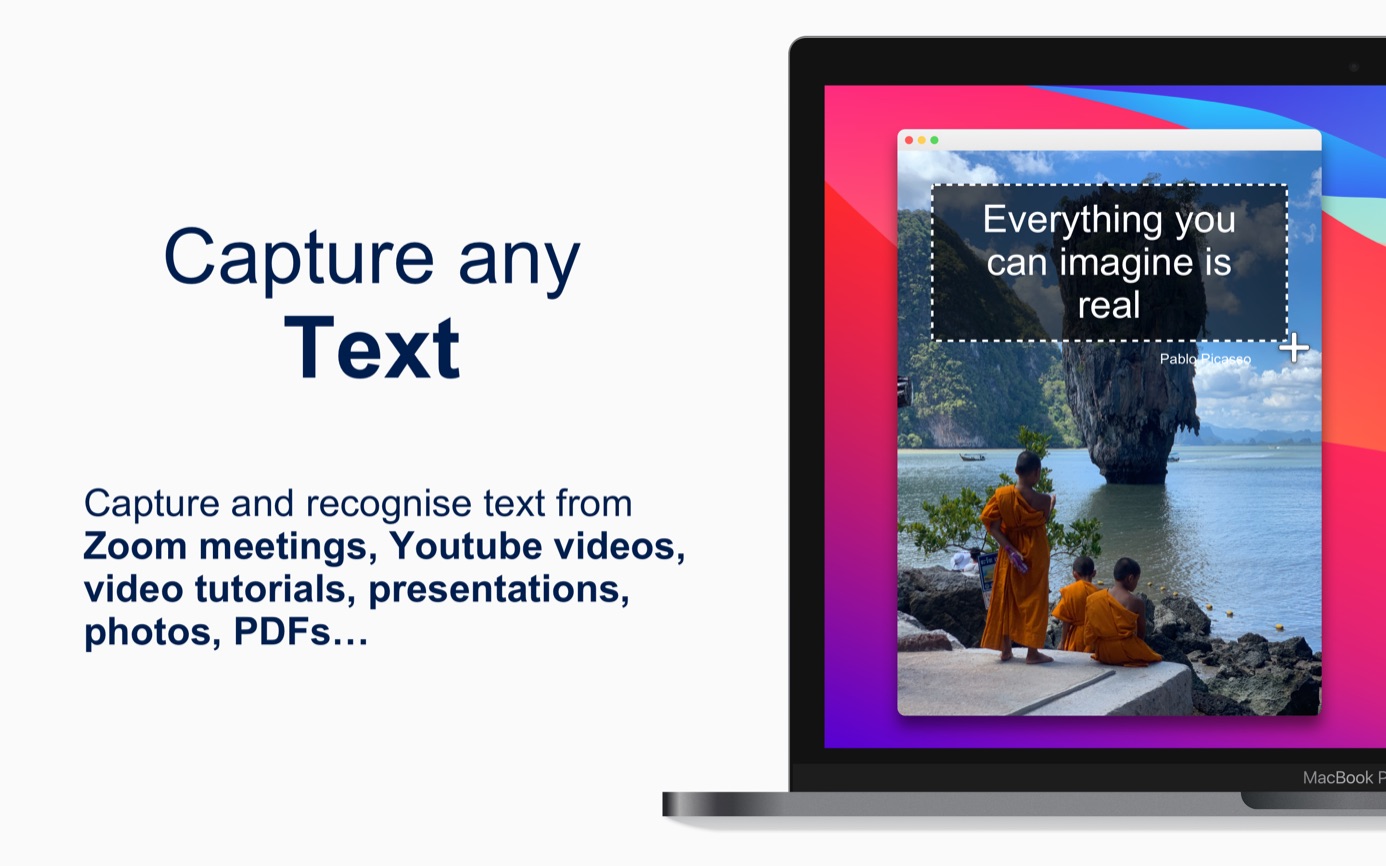
Choose Capture Text in LensOCR and start the capture from the menu or your configured shortcut. Drag around the paragraph you want, including punctuation and complete line endings. If a page has two columns, select one column at a time so the resulting words are easier to assemble in the correct reading order.
Keep page numbers, headers, and footnotes outside the selected area unless you need them in the extract. Press Escape to cancel a mistaken selection. macOS Screen Recording permission is required for LensOCR to capture this screen region. After recognition finishes, paste the text into your document before selecting another passage.
Paste the extract and retain its page reference
Click into your editor and press Command-V. Add a short source note such as the document name and page number before moving to the next page. For research notes, keep quoted passages separate from your own comments. This makes it easier to locate the original later and compare the extract when a detail is uncertain.
For a long passage that spans more than one visible region, capture and paste consecutive sections in order. Check the joining point each time so a repeated line or missing sentence does not slip through. This workflow operates on the region displayed on your Mac screen; it does not process every page of the PDF in one step.
Clean line breaks without losing meaning
Scanned text often has a line break wherever the original page wrapped a sentence. LensOCR's Ignore line breaks option can join recognized lines into a paragraph. That may help when copying prose into a note, while keeping line breaks is useful for a list, an address, or a passage whose line boundaries matter.
Check hyphenated words at line endings and any text near the page gutter. Confirm dates, totals, citations, and section numbers against the scan. For a table, compare each value with its row and column rather than assuming the pasted order preserves the table layout. Rebuild the table in your editor if you need structured rows and columns.
Understand what this PDF workflow produces
The result is text you can paste and edit in another app. The original PDF stays as it was, including any existing image pages. Screen capture does not add a searchable text layer, replace a page, or create a newly searchable PDF file. Keep both the source and your edited extract when you need to preserve the document alongside the words you copied.
Questions about this workflow
How can I avoid mixing columns from a scanned PDF?
Capture one column or paragraph at a time and paste the pieces in reading order. Leave adjacent columns outside the selection, then compare the end of each extract with the start of the next to catch missing or repeated lines.
Will capturing PDF text make the PDF searchable?
This workflow copies recognized text to the clipboard for use in another app. It does not write a text layer back into the original PDF, so searching that PDF will continue to depend on the text it already contains.